Data Leak or Just Coffee? Why Your Connected Devices Need Identity Audits
Learn how data minimization principles and targeted audits help prevent unmonitored connected devices and automated pipelines from over-fetching data.
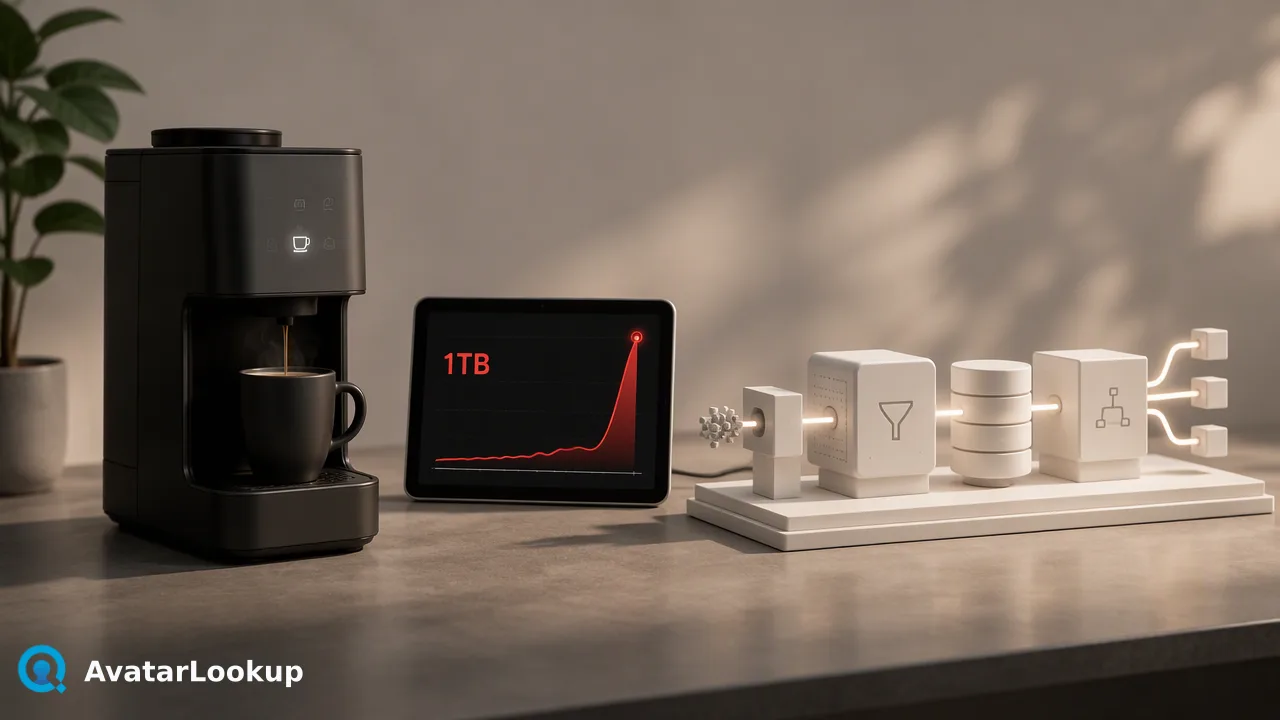
A viral incident of a coffee maker generating 1TB of traffic underscores the operational danger of unmonitored devices and the value of data minimization.
When a viral report revealed a household smart coffee machine generating 1TB of data within 10 days, it highlighted the hidden operational risks of unmonitored connected systems. In automated workflows, background processes and data pipelines can quietly over-fetch, store, and process unnecessary information. The principle of data minimization—formalized under Article 5(1)(c) of the General Data Protection Regulation (GDPR)—stipulates that data processing must remain adequate, relevant, and limited to what is strictly necessary. Conducting routine identity and data audits helps technical teams identify resource bloat, avoid over-fetching, and structure automated queries around deliberate, scoped identifiers.
The 1TB Wake-Up Call
A widely circulated incident where an IT professional discovered his parents' smart coffee machine had generated 1TB of network traffic in 10 days offers a sharp lesson in system visibility. While the investigation indicated that the massive volume stemmed from a device bug saturating the local access point rather than leaking across the wider internet, the scenario demonstrates how easily an unmonitored connected device can silently monopolize resources.
In business environments, automated pipelines often exhibit the same runaway behavior. Automated processes, recurring data pulls, and background enrichment scripts can execute unnoticed for weeks. When these processes run without targeted query parameters or strict traffic thresholds, they generate operational bloat. Unmonitored data ingestion consumes network capacity, inflates database volumes, and complicates compliance postures, reinforcing the practical need for regular audits of connected endpoints.
Data Bloat in Digital Workflows
The transition from physical IoT misconfigurations to enterprise data pipelines is direct. Contact databases, CRM pipelines, and automated lookup queues frequently accumulate redundant records and stale profile parameters. Fetching unneeded attributes or running broad enrichment sweeps across entire contact lists without a clear operational requirement wastes infrastructure resources and elevates governance overhead.
To prevent unnecessary accumulation, regulatory frameworks establish strict requirements for architectural restraint. Under GDPR Article 5 (Regulation (EU) 2016/679), personal data must be adequate, relevant, and limited to what is necessary in relation to the purposes for which it is processed. Applying data minimization principles requires system architects to evaluate every incoming identifier. Teams must establish whether a workflow genuinely requires continuous updates or simply a one-time verification of public profile availability.
Structuring Audits for Automated Data Pipelines
Conducting an audit of automated pipelines requires examining how background integrations request, store, and refresh contact data. Rather than allowing integrations to run open-ended queries, organizations can implement structured evaluation criteria:
Payload Scoping: Inspect incoming API responses to ensure internal storage schemas ingest only essential attributes rather than saving raw, extraneous metadata.
Cadence Calibration: Audit scheduled batch jobs to verify that automated runs correspond to active operational workflows rather than legacy recurring schedules.
Identifier Discipline: Restrict external queries to verified account identifiers or known inputs instead of querying unvalidated directories.
Auditing pipelines against these standards curtails passive accumulation, ensuring every ingested data point serves an active, defined purpose.
Optimizing Data Consumption with Targeted Analysis
Applying data minimization in contact-data workflows means selecting tools configured for specific analytical tasks rather than indiscriminate enrichment. Platforms like AvatarLookup provide algorithmic portrait attributes for contact-data workflows rather than profile or identity verification, analyzing an existing picture or the public avatar associated with a supported identifier.
Teams can structure technical integrations by leading with image profile analysis for existing visual assets, where image attributes are returned as algorithmic estimates. When only an account identifier is available, realtime single-check queries on supported services provide immediate public avatar signals. For larger datasets, asynchronous bulk processing via file upload handles scheduled reviews without overloading synchronous channels.
| Integration Type | Primary Operational Role | Processing Model |
|---|---|---|
| Image Profile Analysis | Evaluates visual attributes from a provided image | Synchronous multipart upload |
| Identifier Avatar Analysis | Checks public avatar signals for specific accounts | Realtime single check |
| Bulk Profile Tasks | Processes planned lists via formatted files | Asynchronous batch task |
Selecting the precise analysis scope helps organizations maintain lean databases and prevents wasteful over-fetching.
FAQ
What is the principle of data minimization under data protection regulations?
Data minimization is a core governance standard, established under GDPR Article 5 (Regulation (EU) 2016/679). It requires that personal data processing is adequate, relevant, and strictly limited to what is necessary for the specified operational purpose. Applying this standard ensures that automated pipelines collect only the identifiers essential to the workflow.
How can organizations identify over-fetching across automated processes?
Organizations can uncover over-fetching by auditing query scopes, payload contents, and background network traffic. Teams should review automated routines to determine whether tasks fetch broad demographic batches when single checks suffice, or whether endpoints ingest unneeded profile fields instead of specific public signals.
Why distinguish between single-check queries and bulk processing?
Selecting the processing mode to match operational requirements prevents unnecessary data accumulation. Realtime single-identifier lookups support immediate, targeted validation tasks, whereas asynchronous bulk processing handles planned, large-scale workflows. Aligning the request format with current operational needs supports system hygiene and limits unnecessary consumption.
Learn More
Choose the product information that fits the next step in your workflow.